
Models
Introducing K-EXAONE 2.5, a large language model, and EXAONE Tabular, a model specialized in structured data, both developed by LG AI Research.
K-EXAONE 2.5
K-EXAONE 2.5 is a high-performance model with particular strength in Korean language understanding and generation. It supports a wide range of software development tasks, including code generation, analysis, and debugging. With its ability to handle long contexts and complex tool calling instructions, it can be applied broadly to business workflows and agentic tasks.
- Intelligence
- Higher
- Speed
- Medium
- Context length
- 512K
- Max output tokens
- 512K
- Knowledge cutoff
- 2026-01
| Model Training | From continual pre-training through post-training, a high-quality synthetic data methodology was applied to raise the quality of model training. In addition, an anomalous data detection system was used to carefully curate and refine the training data, further improving model performance. | ||||||||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Modalities | Text | ||||||||||||||||||||||||||||||
| Languages | Korean / English | ||||||||||||||||||||||||||||||
| Parameters | 750B(Active 31B) | ||||||||||||||||||||||||||||||
| Features | Chat / Tool calling / Structured outputs / Code generation / Streaming | ||||||||||||||||||||||||||||||
| Benchmarks | K-EXAONE 2.5 delivers substantial performance gains over its predecessor across all agentic coding, search, and tool-use benchmarks, while performing on par with open-weight models of comparable scale, such as DeepSeek-V4.1-Flash and GLM-5.3. | ||||||||||||||||||||||||||||||
| |||||||||||||||||||||||||||||||
EXAONE Tabular
- Ranked 1st on TabArena
- 1st in Classification, 2nd in Regression on TabArena Top-tier performance on the leading global benchmark for tabular data
- Ranked 1st Across Benchmarks
- 1st in biomedical classification and regression, and relational data classification, on TabBench, Bio, and RelBench
- Multimodal Extended to Text & Image
- Strong Multimodal Performance on STRABLE and MulTaBench Combines tabular data with text and image embeddings for more accurate predictions
- 21M Small Model, Exceptional Performance
- Top-Tier Accuracy at 1.3% the Size Delivers top-tier predictive performance with roughly 1.3% of the parameters of Google TabFM
Upon its v1 release, EXAONE Tabular ranked 1st in classification and 2nd in regression on TabArena, a global benchmark for tabular data AI, demonstrating world-class predictive performance.
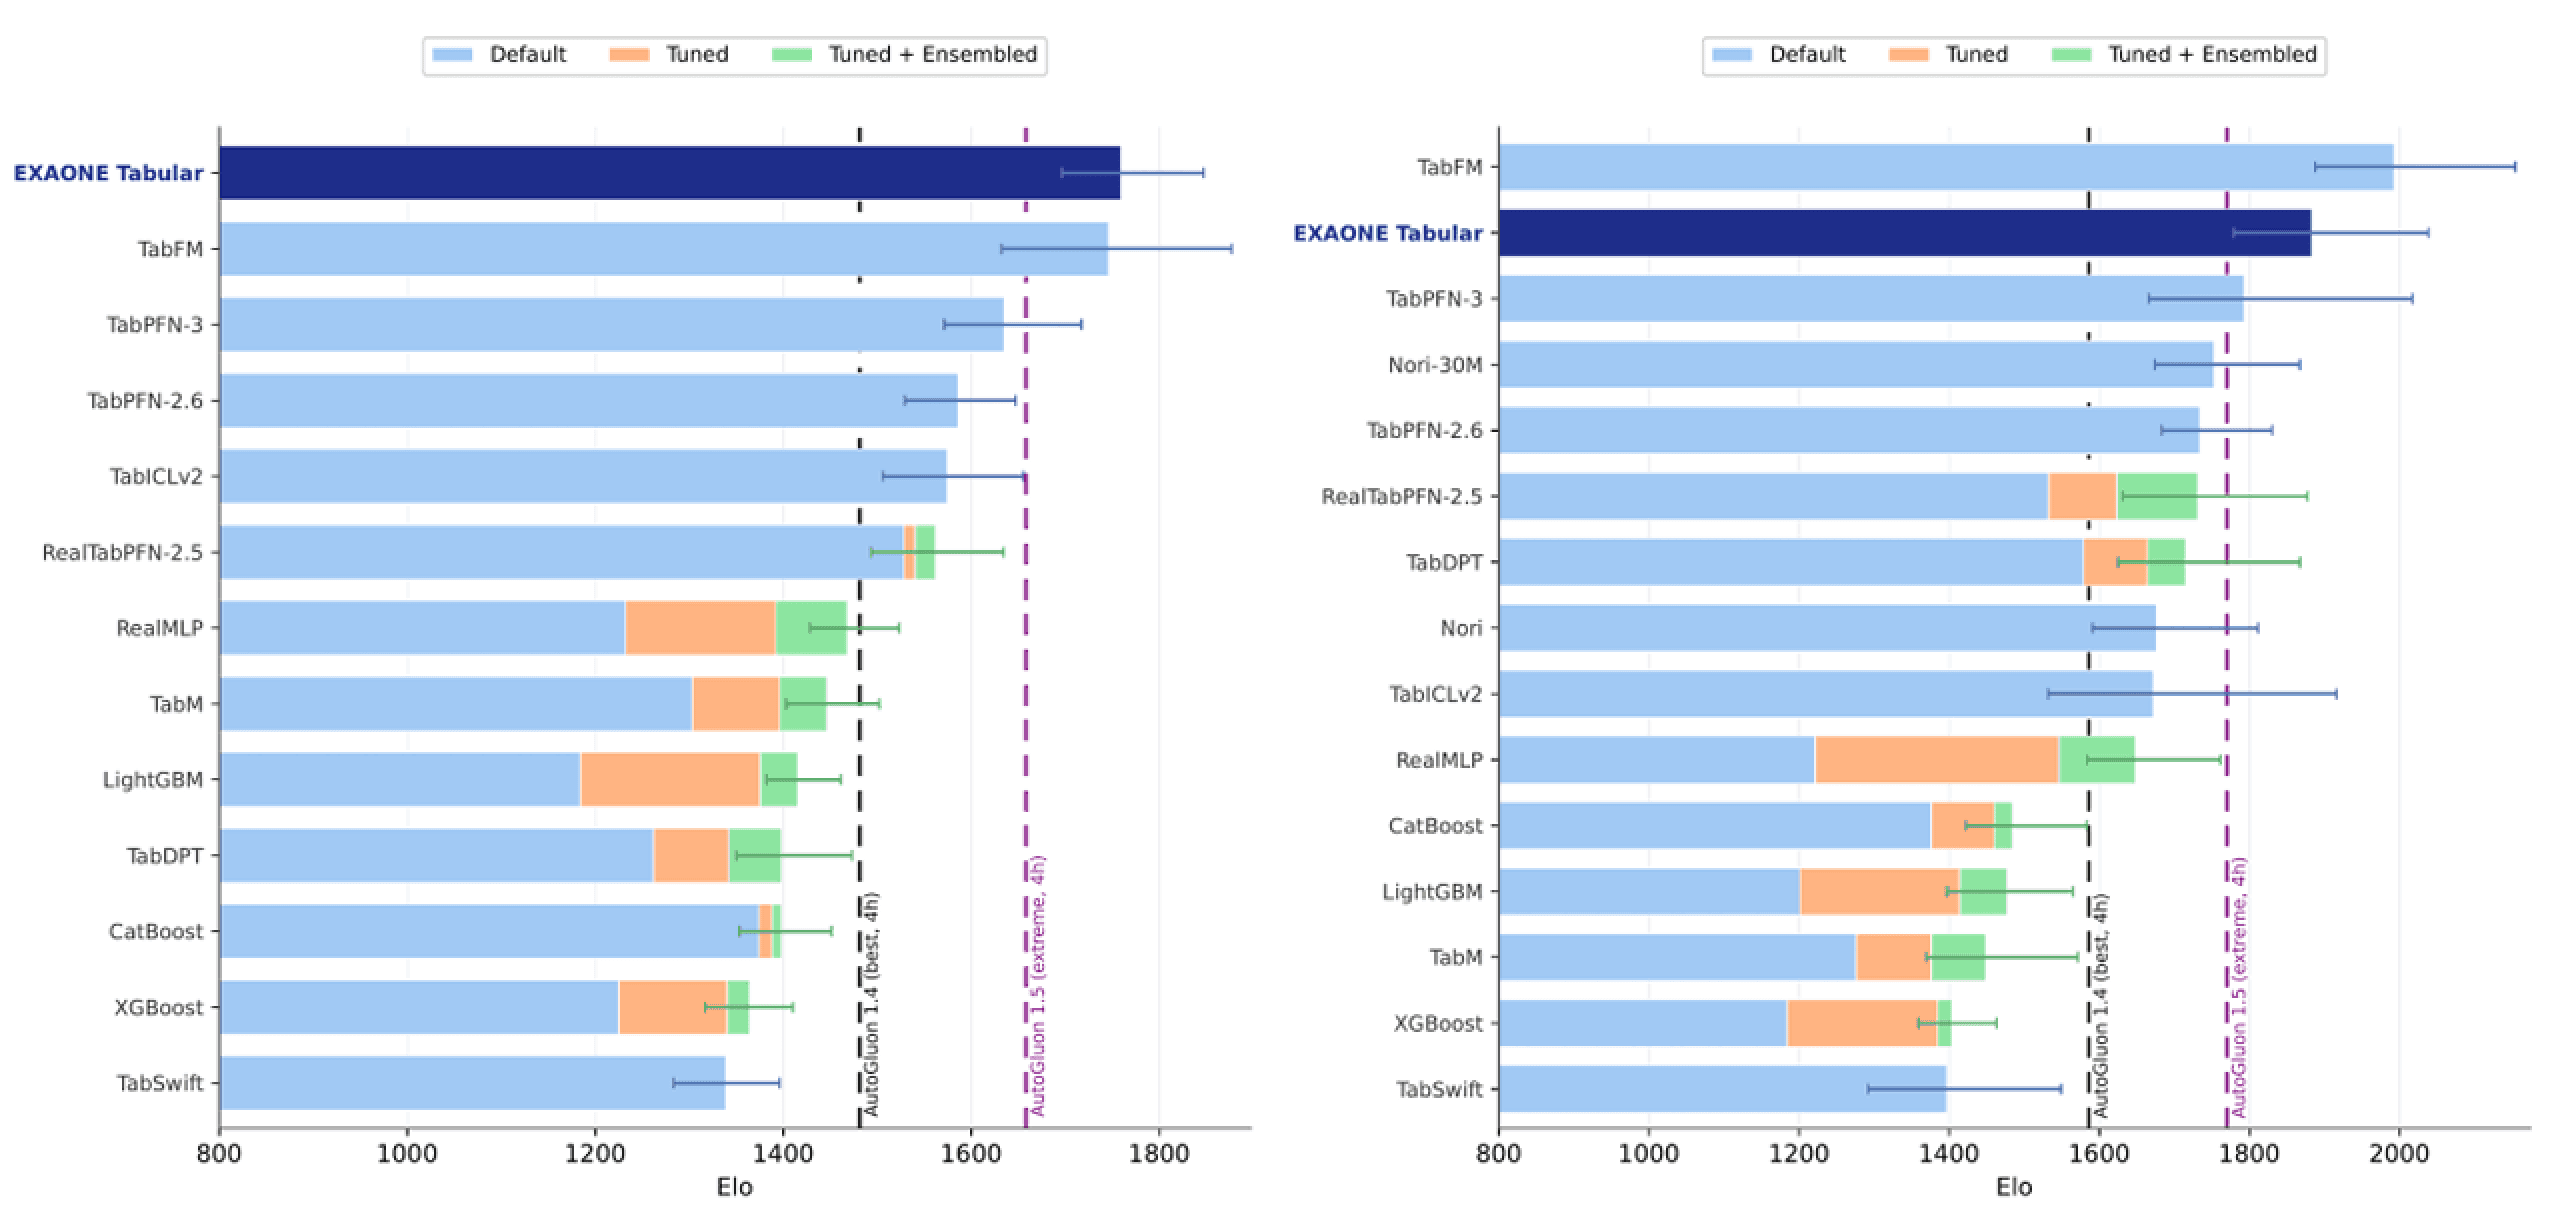
It also took 1st place in both classification and regression on TabBench-Bio and in classification on RelBench, proving its strong competitiveness across a wide range of prediction tasks.
EXAONE Tabular achieves this level of performance with just 21 million parameters. At roughly 1/78 the size of Google's tabular foundation model, TabFM, it delivers high predictive performance, combining accuracy with efficiency.
Beyond tabular data, EXAONE Tabular can also leverage text and images. By combining text and image embeddings with tabular data, it achieves top-tier results on leading multimodal benchmarks such as STRABLE and MulTaBench.